Seniorenbetreuung Lala: landing page with an AI chat
Problem
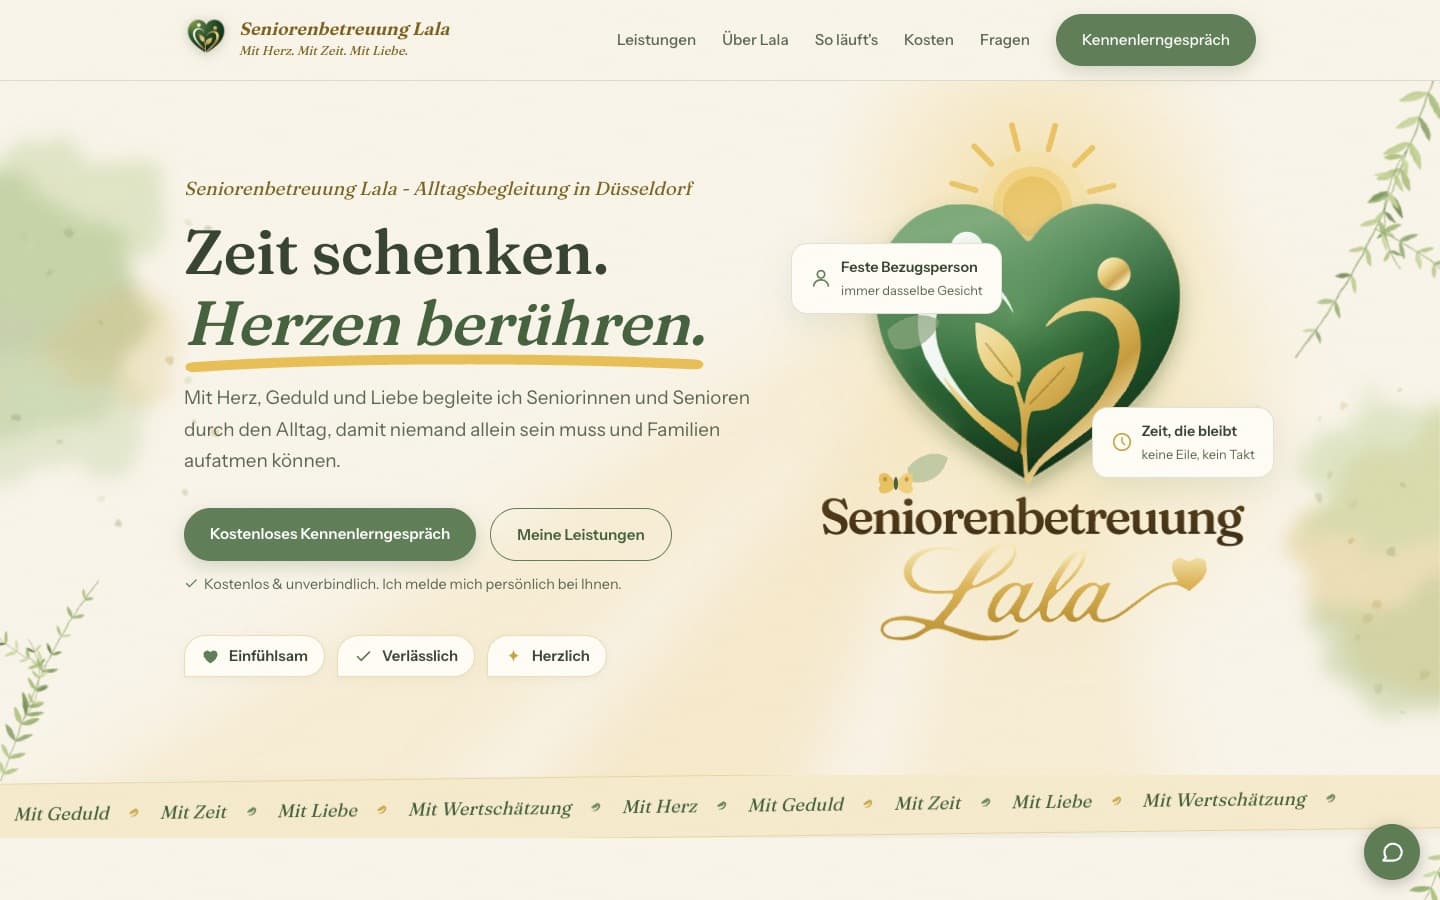
Seniorenbetreuung Lala offers everyday companionship for older people in Düsseldorf. The owner works alone, and many enquiries come from relatives. The need was a calm, readable page and a chat that answers questions about the care, the service area and costs around the clock. It may only state verified facts, must never invent prices or give medical advice, and has to be clearly marked as AI.
My role
I designed the page, configured the agent and set up domain, hosting and security headers. The chat platform behind it is my own voice and chat agent platform. Copy and business details came from the owner. I wrote the specs, reviewed every change, tested with Lighthouse and a chat test run before launch, and decided what went live.
Approach
The page is static HTML with no build step, self-hosted fonts subset to the characters in use, and GSAP for the animations. Without JavaScript or with reduced motion, everything is visible right away. Vercel serves it with strict headers: the Content Security Policy allows scripts and connections only from the site's own origin, and the two inline scripts run via SHA-256 hashes. The chat widget loads only when the browser is idle after page load; a placeholder remembers an early click on a chat button.
The chat runs on my voice and chat agent platform. A rewrite in vercel.json forwards /api/chat/* on the server side, so the browser only talks to the site's own domain. The agent is pure configuration: a persona with guardrails (details on care and costs only from the knowledge base, no invented promises, no medical advice, 112 in an emergency), retrieval over a Markdown knowledge file, prompt rules against appointment and callback promises, and an output filter that replaces any booking promise that still slips through, because the chat forwards nothing. The first reply carries the AI notice. Since 26 Sep 2026 the chat uses a free model via OpenRouter with a list of fallback models against overload (HTTP 429), then Groq as a second provider.
Architecture
Visitor on seniorenbetreuung-lala.de
Static page on Vercel with GSAP. chat.js (9 KB) loads only when the browser is idle.
Vercel rewrite /api/chat/*
Same origin, CSP with connect-src 'self'. The platform is connected on the server side.
Web chat API (FastAPI)
Origin allowlist, 20 messages per minute per IP, 500 per day per agent, at most 400 tokens per reply.
Prompt assembly
Persona with guardrails, chat rules and hits from the knowledge base (LanceDB, top_k 4).
Language model
OpenRouter with a list of free models against HTTP 429, then Groq as a different provider.
Output
Filter against booking promises, AI notice before the first reply, chat histories deleted after 30 days.
Decision
Same origin via rewrite instead of a third-party script
I could have loaded the widget straight from the platform domain. Instead, a frozen, neutral copy (9 KB) lives in the site's repo, and vercel.json forwards /api/chat/* on the server side. That way 'self' is enough for script-src and connect-src, there is no CORS, and the page source and network tab only show the site's own domain. The cost: changes to the platform widget no longer flow over automatically. And behind the rewrite, GET requests arrive without an Origin header. So the server tolerates a missing Origin only on the read-only GET routes, never on chat messages, which trigger a model call.
Code excerpt
telefon: false
persona: |
  [...]
  Fragen zu [...] Einzugsgebiet und Kosten beantwortest du
  ausschließlich mit der Wissenssuche; du erfindest niemals Preise oder
  Zusagen. [...]
  Ganz wichtig: Seniorenbetreuung Lala leistet KEINE medizinische oder
  pflegerische Versorgung und du gibst niemals medizinischen Rat. Wird
  akute Hilfe benötigt, verweise ruhig und deutlich auf den Notruf 112.
llm:
  provider: openrouter
  # Gratis-Modelle sind oft kurz überlastet (HTTP 429): 'models' lässt
  # OpenRouter der Reihe nach auf die nächsten freien Modelle ausweichen
  model: nvidia/nemotron-3-ultra-550b-a55b:free
  options:
    extra:
      extra_body:
        models:
          - nvidia/nemotron-3-ultra-550b-a55b:free
          - google/gemma-4-31b-it:free
          - qwen/qwen3.8-27b:free
llm_fallback:  # anderer Dienst als der Primary
  provider: groq
model: openai/gpt-oss-120bResults
- 94Lighthouse performance on mobile, measured locally (desktop 100), 22 Aug 2026
- 100Lighthouse accessibility and best practices against the live URL, 22 Aug 2026
- 57 KBFonts after subsetting, previously 126 KB
- 9 KBChat widget, loads only when idle after page load
- 0
- CSP violations when clicking through, chat included (local replica of the deployment)
- 30
- days retention for chat histories, active on the server since 22 Aug 2026
What I learned
I maintain the page copy and the chat's knowledge base separately, so every change to the page has to be carried over to the knowledge base by hand. Today I would feed both from one source or index the page itself. One sentence on the page also promised a personal reply while an AI answers. I fixed that on 26 Sep 2026, and since then I check page copy against what the system actually does. I still update the CSP hashes by hand when an inline script changes. Today I would generate them in a small build step.